DeepSeek V4.1 Flash Arrives in Selectel's Token Factory Catalog
Selectel has added DeepSeek V4.1 Flash to Token Factory. The open model offers a one-million-token context and runs in Russian data centers.
 SUMO· the number puzzle
 Dialo· learn languages by speaking
 ediviewer· read EDI files like documents
 giftdetect· the right gift in minutes
Selectel has added DeepSeek V4.1 Flash to the catalog of Token Factory, its pay-per-token inference service. The model is the October update of the open model from Chinese lab DeepSeek, whose weights were released on 17 October under the MIT license. It is served through the same OpenAI-compatible API as the rest of the catalog, and requests are processed in Russian data centers.
What the model offers
DeepSeek, based in Hangzhou, has repeatedly pushed down API prices with its open models. The base V4.1 Flash appeared in September, and the company itself calls the 1017 version a minor update. It is a mixture-of-experts model with 763 billion parameters, of which about 16 billion are active per generated token, roughly 2% of the network. That is why a model of this size responds at the speed of much smaller ones.
The main engineering feature is a frugal KV cache: in FP4 it takes 890 bytes per token, four times less than V4 Flash. This makes memory scale efficiently with a context of one million tokens, 2.7 times larger than V4 Flash. The model is multimodal, with images handled by DeepSeek-ViT, an encoder trained from scratch. DeepSeek promises higher benchmark results, faster task execution and shorter answers, which matters under per-token billing. The technical report shows an 11-point gain on Terminal-Bench, and in automation and web-development tests the lightweight Flash outperformed the heavier Opus.
Cost and data handling
For a typical agent request with 50,000 input and 2,000 output tokens, the cost is about 13 rubles without caching. If 40,000 input tokens hit the cache, such as a repeated system prompt and tool descriptions, it falls to about 5.8 rubles.
The practical rule: V4 Flash remains cheaper for chats, classification and bulk text processing, while version 1017 makes sense when a whole repository, a long conversation or scanned documents must stay in memory. All requests stay inside Russian infrastructure. According to the documentation, prompts and responses are not stored or used for model training; only technical consumption statistics are collected. For projects with personal data, that is likely the main argument for local inference over DeepSeek's direct API.
To connect, open Products → Token Factory in the control panel, create an API key and copy the model alias deepseek-v4.1-flash-1017 from the model catalog. Because the API is OpenAI-compatible, existing code only needs a new base_url and model name. DeepSeek recommends temperature and top_p of 1.0.
Apps worth a look
SUMO: the number puzzleTap the right tiles, add them up, hit the target. Easy to learn, hard to master. Free, for all ages.
Dialo: learn languages by speakingTalk to an AI conversation partner; every sentence comes back corrected and explained in your language. 9 languages, A1 to C2.
ediviewer: read EDI files like documentsOpen EDIFACT and X12 messages, see every segment explained, convert to JSON/XML, export PDF and Excel. Runs locally, no upload.
giftdetect: the right gift in minutesPick who it is for, the occasion and their personality. The search engine reads product descriptions from local shops and ranks what fits. Free, no sign-up.
More from this day
See all →
Shield AI to Acquire Radar Maker Echodyne for $5.3 Billion
Zipline Raises $1.5 Billion at $21.5 Billion Valuation
Russia's Central Bank Approves Bitcoin, Ethereum and USDT for Exchange Trading

Beget Restores 60% of Hosting After Cyberattack, Cloud Lost
More in: AI
See all →
NCBR Sets Aside PLN 25 Million for International AI R&D Projects
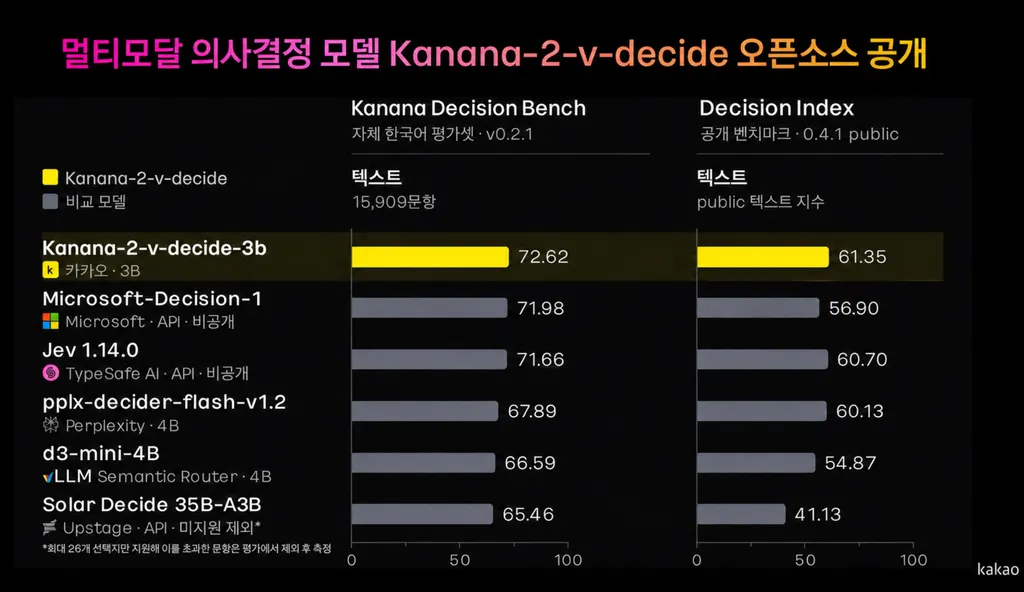
Kakao Open-Sources Kanana-2-v-decide, a Decision Model for AI Agents
Airbnb Is Building an AI Travel Agent for a 2027 Launch