Sber Releases Kandinsky Avatar 1.0 as Open-Source Talking Avatar AI
Sber has opened access to Kandinsky Avatar 1.0, a model family that turns a photo and a voice recording into talking video avatars up to one minute long.
Sber has opened access to Kandinsky Avatar 1.0, a family of neural networks that generates talking video avatars from a single photo and an audio recording. The models produce clips of up to one minute at 24 frames per second, the company said.
The system syncs lip movement with speech and adds facial expressions, head turns and gestures on its own. To make a video, a user supplies a photo, an audio track and a short text description of the scene. Emotions such as joy, sadness or anger can be set with a text prompt. Speech plays in the language of the source recording. Kandinsky Avatar does not generate or clone voices, so the audio must be provided separately.
Open code under the MIT license
Code and weights are published under the MIT license on GitHub, GitVerse and Hugging Face. Developers can download them for free and use them in their own projects, including commercial ones. Sber also plans support in popular tools for working with third-party neural networks, and intends to bring video avatars to its own services.
The company lists several uses: tools for bloggers with virtual presenters, educational platforms with digital teachers, virtual customer consultants, video localization with synchronized lip movement, game and animation characters, and personalized video greetings.
Pro and Lite versions
Kandinsky Avatar is built on the Kandinsky 5.0 Video generation model and comes in two versions. Pro outputs HD video. In Sber's internal comparisons, it matches the quality of the commercial service HeyGen and beats the open alternatives tested. Lite targets weaker hardware and can run on a home graphics card, but produces SD-resolution video.
The models were trained on more than a million video clips, including interviews, talks and podcasts in 95 languages such as Russian, English, Kazakh, Spanish and French.
"We are opening the model so that Russian developers have their own technological foundation for such solutions," said Denis Dimitrov, managing director for data research at Sberbank. He said developers can embed it in products and fine-tune it for specific tasks without building the technology from scratch. Sber expects developer feedback and plans to use it to improve future versions of Kandinsky.
Apps worth a look
 SUMO: the number puzzle
Tap the right tiles, add them up, hit the target. Easy to learn, hard to master. Free, for all ages.
 Dialo: learn languages by speaking
Talk to an AI conversation partner; every sentence comes back corrected and explained in your language. 9 languages, A1 to C2.
 ediviewer: read EDI files like documents
Open EDIFACT and X12 messages, see every segment explained, convert to JSON/XML, export PDF and Excel. Runs locally, no upload.
More from this day
See all →
Vitroscope raises $7M to keep living human tissue alive in labs
Tallia raises €4 million Seed to bring AI research to tax firms
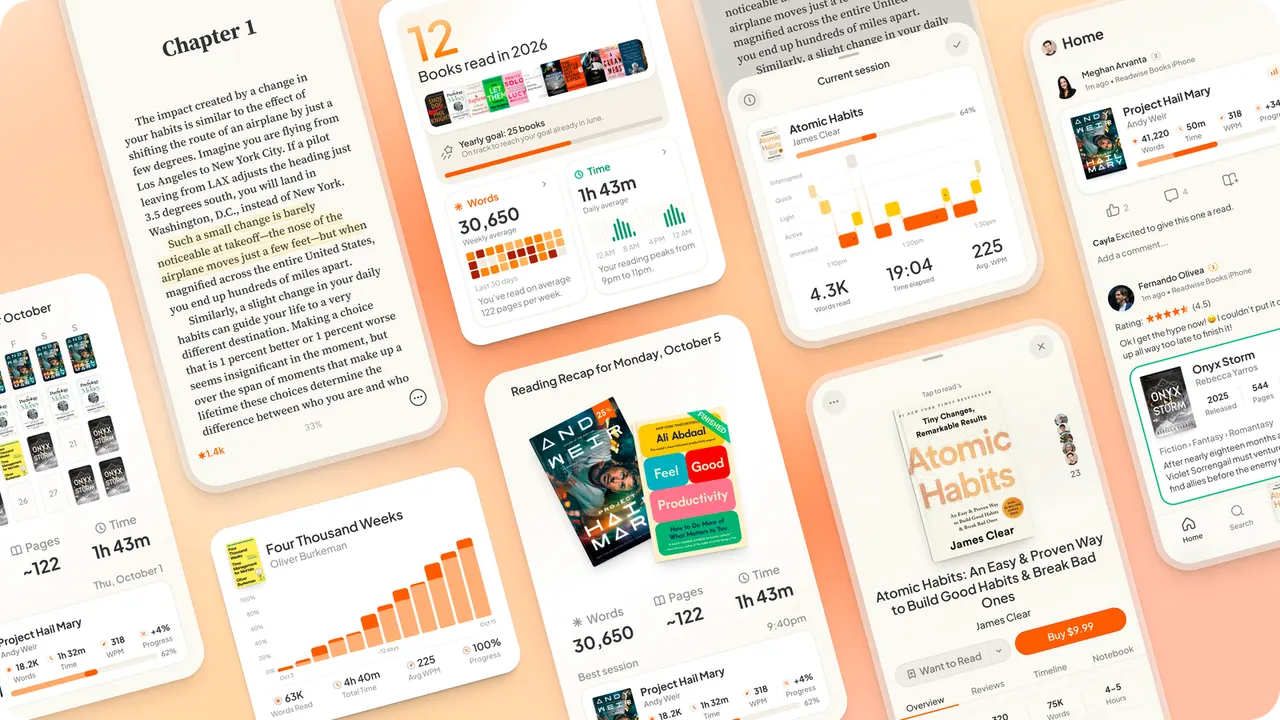
Readwise Books launches as a Kindle and Goodreads rival
42AI exits stealth with $62.5M for a behavioral world model
More in: AI
See all →
Google launches Dreambeans, an experimental AI story app, in India
MeitY Unveils EKA-1, Dhīr 2B and Dhīr 5B AI Models Under IndiaAI
Yandex Delivery Rovers Get 40% Faster With AI Motion Planner