Timeweb Cloud outage: a routing restart took servers offline
Timeweb Cloud was unreachable for under two hours on 17 November. The servers kept running. A security update left their routes unannounced.
 SUMO· the number puzzle
 Dialo· learn languages by speaking
 ediviewer· read EDI files like documents
 giftdetect· the right gift in minutes
The Timeweb Cloud outage on 17 November had an odd feature: the virtual servers never actually stopped. They simply became impossible to reach. The hosting provider has now published its explanation, and it comes down to one service that restarted only halfway.
Between 13:18 and 15:05 Moscow time, sites and VPS (virtual private server) resources of Timeweb customers stopped responding. The affected locations were St Petersburg, Moscow, Germany, the Netherlands and Kazakhstan. Only Novosibirsk was spared.
What caused the Timeweb Cloud outage?
Engineers were updating the network stack of the hypervisors, the software layer that runs virtual machines, to improve security. During the update the dynamic routing service did not restart completely. As a result the hypervisors could not re-announce their routes to the network equipment, and part of the servers lost network connectivity. The virtual servers themselves kept working.
How the recovery went
According to the company, problems began at 13:18. By 13:28 engineers had located the issue and started restoring service. At 13:47 Timeweb reported trouble in the SPB, MSK, DE, NL and KZ zones. The fix was a full restart of the hypervisors' network stack, after which routing came back. Most servers were reachable again at 14:17, and everything was restored at 15:05.
Timeweb's first public statement, made before the postmortem, only said the problem was in network equipment and that a full analysis would follow.
What changes
The company lists three changes. After hypervisor updates it will check every component of the routing service, not just the service as a whole. It will lengthen the pauses between update stages, so a fault shows up before the update moves to the next nodes. And it will speed up recovery of the network stack in similar failures.
For customers the practical lesson is a familiar one: a server that is running is not the same as a server that is reachable.
Apps worth a look
SUMO: the number puzzleTap the right tiles, add them up, hit the target. Easy to learn, hard to master. Free, for all ages.
Dialo: learn languages by speakingTalk to an AI conversation partner; every sentence comes back corrected and explained in your language. 9 languages, A1 to C2.
ediviewer: read EDI files like documentsOpen EDIFACT and X12 messages, see every segment explained, convert to JSON/XML, export PDF and Excel. Runs locally, no upload.
giftdetect: the right gift in minutesPick who it is for, the occasion and their personality. The search engine reads product descriptions from local shops and ranks what fits. Free, no sign-up.
More from this day
See all →
Honda RN0: the motorcycle maker's first e-MTB weighs 24 kg
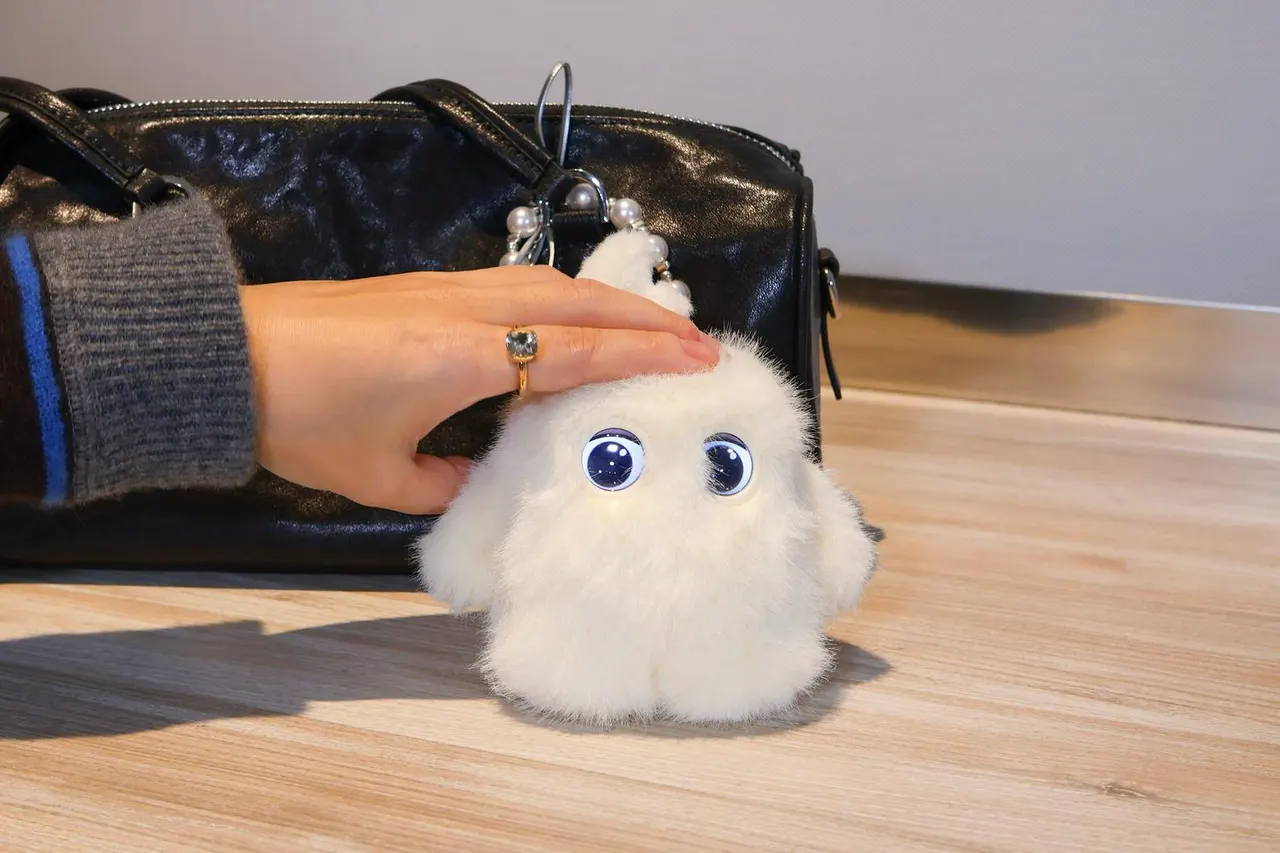
SwitchBot KATA Friends mini: a fluffy AI pet that runs your home
AI avatar YouTube channel gets 100 dislikes and 10 likes
Windows 11 telemetry flags Codex and Claude, even a renamed cmd.exe
More in: Web & Dev
See all →
YouTube copyright claim on Bre Petrunko: a folk singer fights back
Search Robert Pattinson on Google and lemon zest rains down
Archive of Our Own is back online after two weeks offline