OpenAI, Google, Microsoft, Anthropic Plan robots.txt AI Standard
OpenAI, Google, Microsoft and Anthropic are drafting a shared robots.txt specification that lets site owners allow or refuse AI training, with rollout planned from 2027.
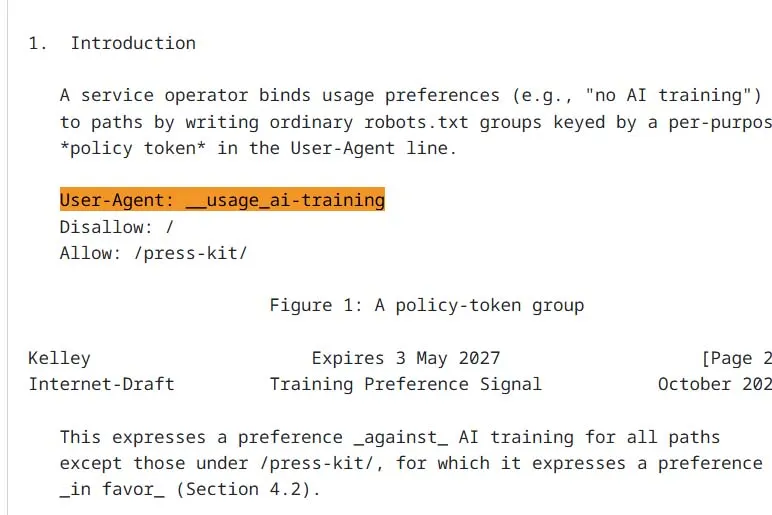
OpenAI, Google, Microsoft and Anthropic have announced they are developing a common specification that will let website operators state in robots.txt whether their content may be used for AI training. The companies aim to introduce it in 2027.
Robots.txt is the file that tells crawlers, the automated tools that collect information from sites, which pages they may access. Operators can use it to permit or block search and AI services. In practice, however, AI services have often ignored the file, and in Japan the newspaper association has raised the problem.
One signal instead of many rules
Until now, site owners have had to identify each crawler individually and manage separate rules for every company. The new effort is meant to reduce that burden by having providers respond to a shared industry signal.
According to Google, site owners will be able to use a common "policy token" in robots.txt to set preferences across all participating AI providers. Google gave an existing example: with its Google-Extended mechanism, a publisher can stay in search crawling while refusing use of its content for training Gemini. The new work aims to turn that kind of setting into a shared robots.txt mechanism.
The specification will be discussed and drafted in the AI Preferences working group of the Internet Engineering Task Force (IETF).
Timelines and company-specific controls
Google plans to adopt the standard in 2027. OpenAI says it aims to do so within the next few months, and Microsoft will apply it from February 2027.
The companies will keep their own crawler controls alongside the common standard. Google says finer-grained settings will still go through Google-Extended, while Microsoft plans to add page-level training settings and a separate grounding setting.
For publishers, a single set of instructions could simplify management. Whether crawlers actually honor those instructions will remain the key test once the standard arrives.
More from this day
See all →
Amazon Echo Time, Dot and Studio: Alexa Plus Gets New Hardware
Google halts Finland data center work after 250,000 trees felled
Apple CEO John Ternus on AI: Happy With Apple's Position